The problem
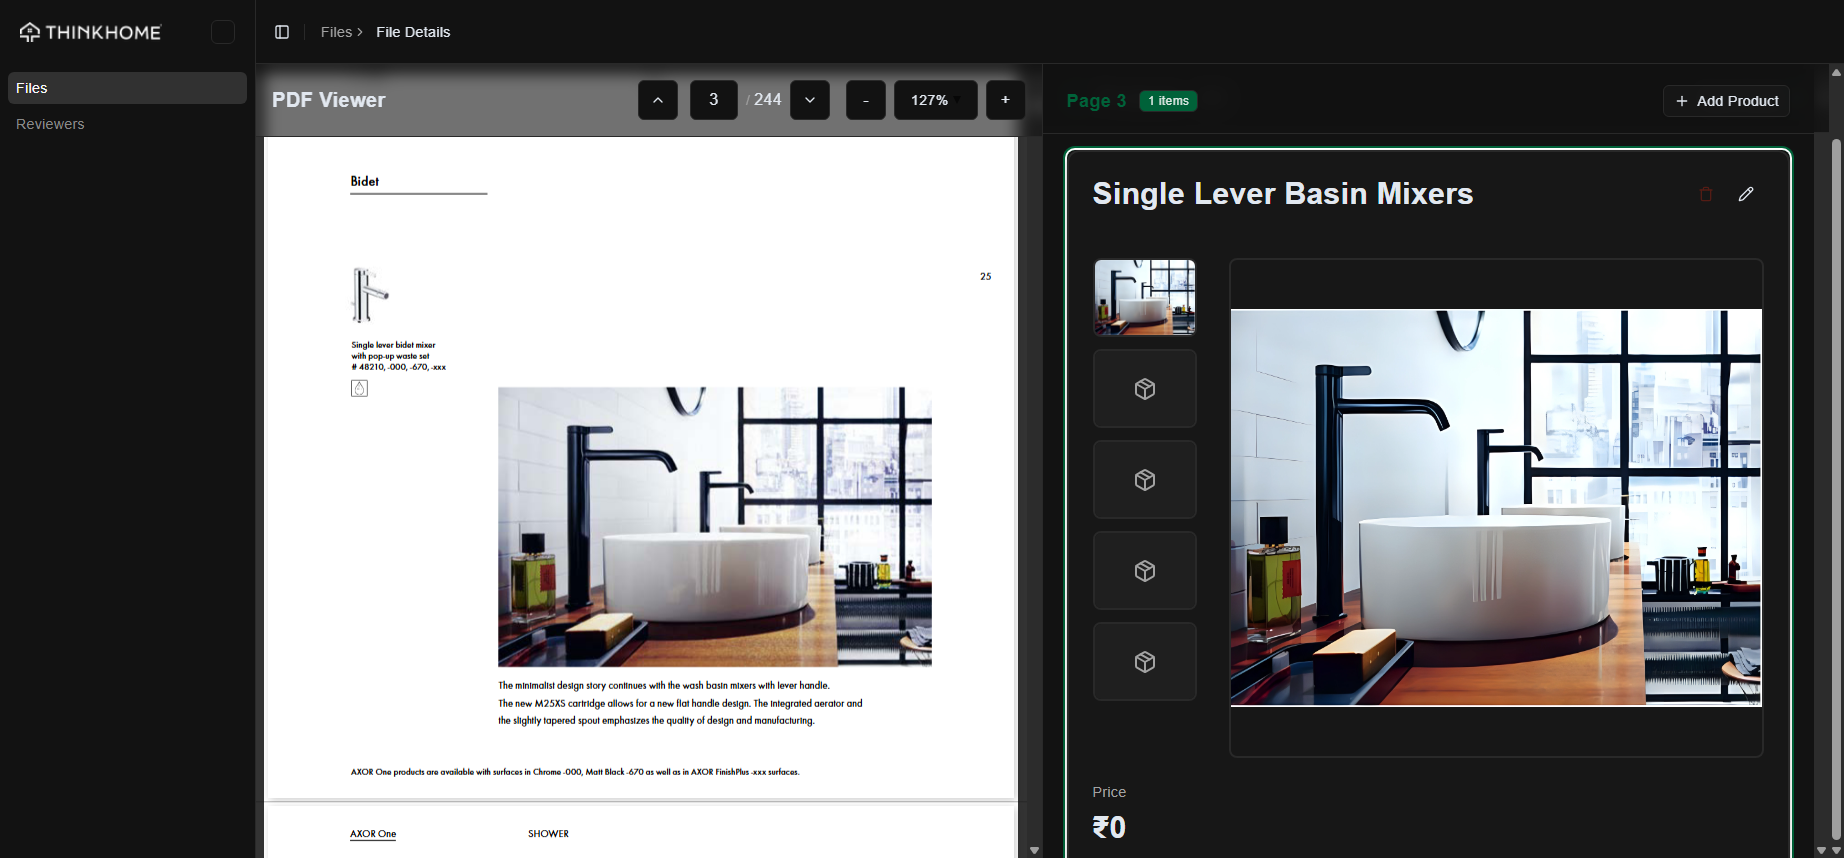
Product catalogues often arrive as PDFs, where images and specifications are difficult to reuse in an online store. Thinkome PDF Extractor was built to move that information into a structured workflow: process the document, identify products and their images, extract metadata, and let a person review the output.
What I built
I designed and developed the Python backend pipeline using Qwen3 on Modal, including image processing and metadata extraction. The implementation separates page work from product work, coordinates queued jobs, and records progress so processing can resume from unfinished stages after a failure instead of starting an entire catalogue again. I also built a Next.js and Supabase admin interface for inspecting extracted results.
- The pipeline turns unstructured catalogues into product records that reviewers can check and use. It was in testing when described in a December 2025 proposal; a production release or measured extraction accuracy has not been confirmed.